Inference.ai
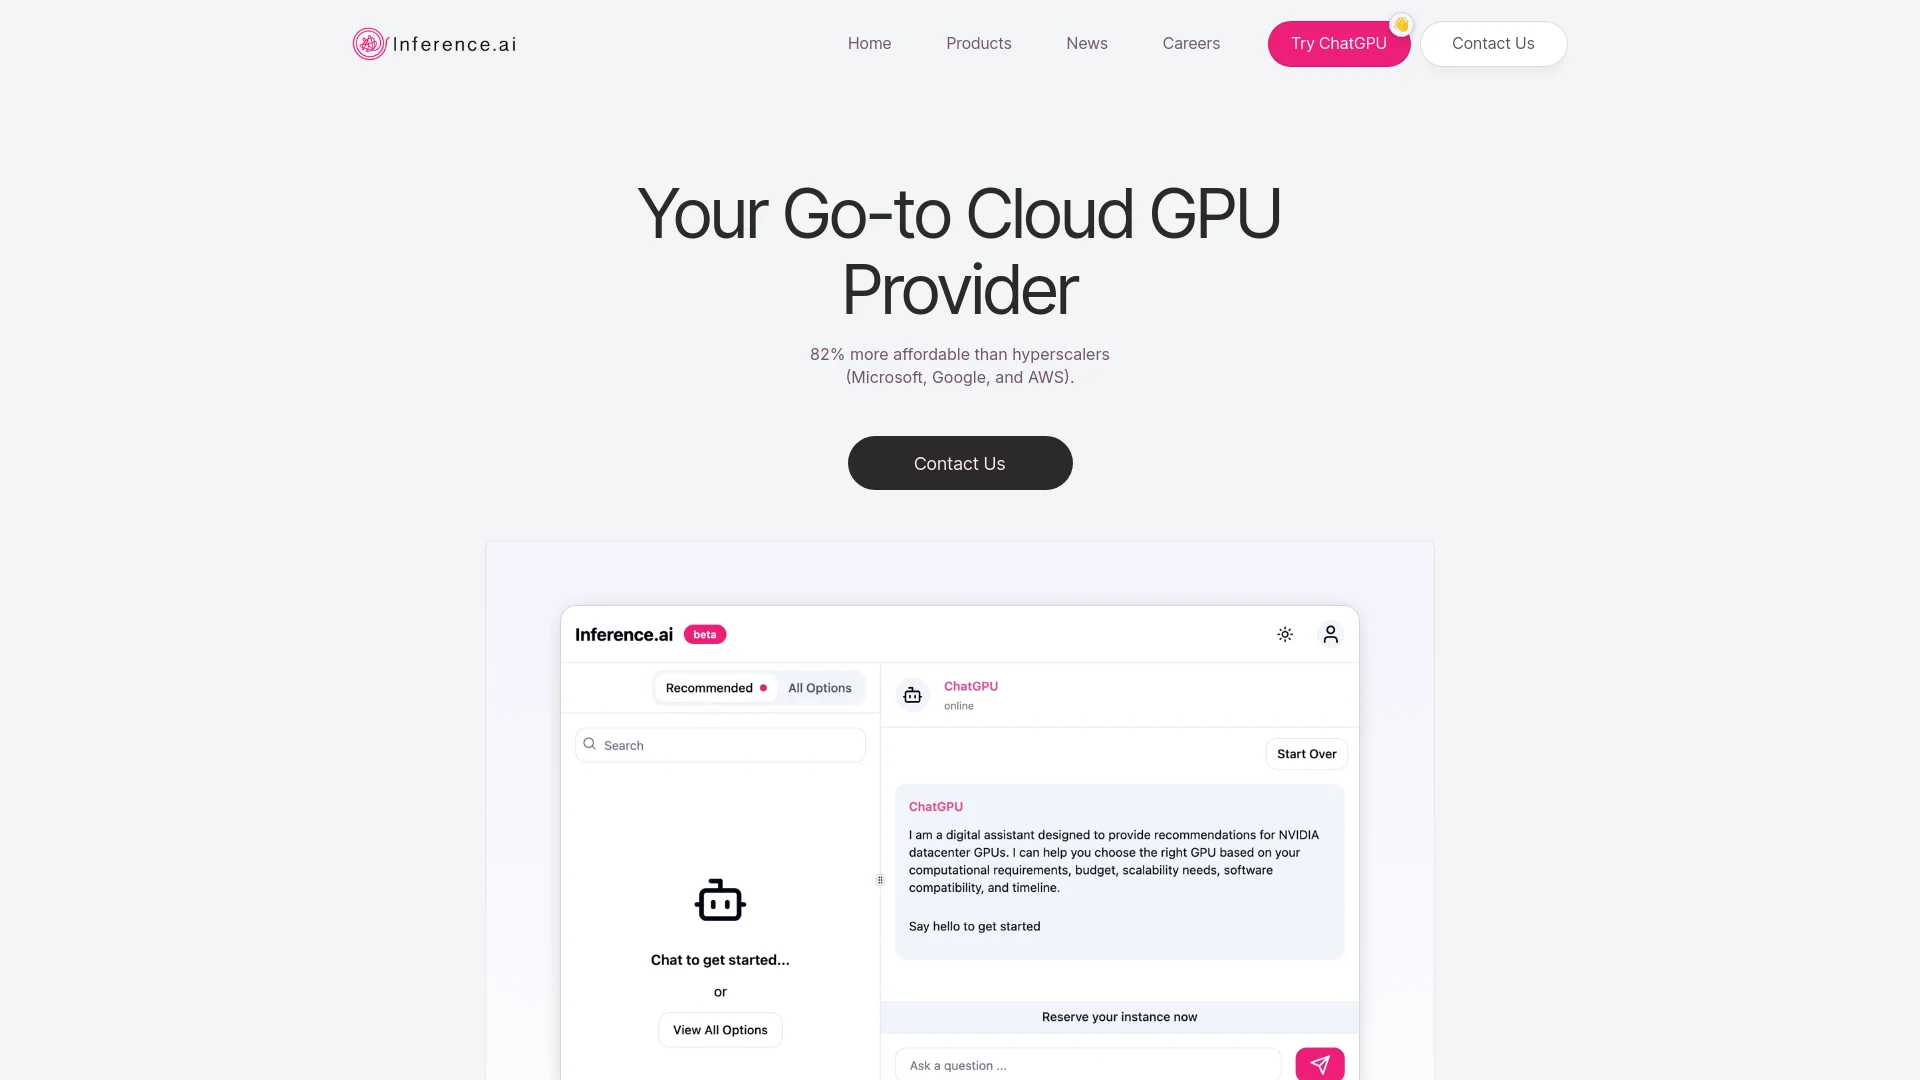
Revolutionize computing with scalable, affordable GPU cloud access.
Key Takeaways
- What it is
- Revolutionize computing with scalable, affordable GPU cloud access.
- Best for
- Access to a Wide Range of NVIDIA GPUs
- Global Data Centers
- Cost Efficiency
- Rating
- 4.8/5
What is Inference.ai?
In the dynamic world of artificial intelligence and machine learning, access to powerful computing resources is a must. Enter Inference.ai, a cutting-edge GPU cloud provider that revolutionizes the way businesses and individuals access and utilize graphical processing units (GPUs). By offering a scalable, affordable, and efficient GPU cloud, Inference.ai caters specifically to those in need of substantial computing power without the overhead of managing physical hardware. Whether you're a data scientist, AI researcher, or a business leveraging machine learning, Inference.ai ensures that you have the computing resources you need, precisely when you need them.
Inference.ai stands out by offering an unparalleled range of NVIDIA GPU options at significantly lower costs than its competitors. Its global reach with data centers around the world ensures that users everywhere can access top-tier computing resources with minimal latency. The platform's focus on removing the burden of infrastructure management from users makes it a particularly appealing choice for those looking to concentrate fully on developing and optimizing their AI models.
Inference.ai excels in providing robust, scalable, and cost-effective GPU cloud solutions, making it an essential tool for anyone involved in data-intensive computing. Its ability to offer a wide range of the latest NVIDIA GPUs at competitive prices, combined with a global infrastructure, offers an unmatched advantage for users worldwide. The focus on user-centric features and support ensures a seamless and productive experience for all its users.
Who is Using Inference.ai?
AI Researchers
Utilizing the platform for running complex machine learning models and simulations.
Large Enterprises
Employing cloud GPUs to handle extensive data processing tasks and AI-driven analytics.
Startups
Leveraging affordable GPU access to innovate and develop new AI-based products.
Educational Institutions
Using cloud GPUs to teach advanced courses in machine learning and data science.
Uncommon Use Cases
Used by animation studios for rendering high-resolution graphics; utilized by financial analysts for real-time trading algorithms.
Key Features
Rating Breakdown
Pricing Plans
Customized Quotes
- Due to the varied nature of GPU requirements
- Inference.ai provides personalized pricing based on specific needs
Which Inference.ai plan should you pick?
Start with Base for a low-commitment always-on agent, then contact support if you need more capacity.
Base
Good for users who need up to two concurrent agents, connected messaging channels, and discounted model usage without a monthly platform charge.
Inference.ai Use Cases
Inbox triage
Ghost can organize an inbox and map out the user's day.
Outcome: A prioritized inbox and daily plan.
Software development
Ghost can build, debug, and ship code on its persistent VM.
Outcome: Long-running development work completed without babysitting.
Reports
Ghost can draft and deliver daily reports.
Outcome: Reports delivered while the user is away.
Messaging-based assistance
Users can interact with an agent through Discord, Telegram, WhatsApp, Lark, or Gmail.
Outcome: The same persistent agent is available across connected channels.
Overnight task execution
Ghost continues working while the user is disconnected or asleep.
Outcome: Tasks are ready when the user returns.
Workflow Ideas with Inference.ai
Deploy an always-on agent
- 1Sign up and provision the VM
- 2Connect Discord, Telegram, WhatsApp, Lark, or Gmail
- 3Send a task and let the agent execute and report back
Customize the agent environment
- 1Connect to the VM through the Inference CLI
- 2Install packages or add scripts through SSH
- 3Run the customized agent continuously on the dedicated VM
Use the model gateway
- 1Open the console from Settings → API access
- 2Create an API key with limits and allowed models
- 3Use the key against the available model gateway
How Inference.ai fits into your stack
API Access
Developers can integrate their systems with Inference.ai's services through a well-documented API.
Cloud Compatibility
Seamlessly works with major cloud providers to ensure that users can integrate their existing cloud services.
Data Security
Implements robust security measures to protect user data across all points of interaction.
Real-Time Data Processing
Supports applications requiring real-time data processing capabilities.
Pros
- +Accelerated Training Speed: Facilitates rapid model experimentation and iteration, significantly reducing development time.
- +Reduced Cost: Notably lower expenses compared to traditional GPU access, making cutting-edge technology accessible to more users.
- +Ease of Use: Simple interface and access procedures ensure that even those new to cloud-based GPU usage can start without a steep learning curve.
- +Comprehensive Support: Inference.ai offers expert advice on the most efficient and optimized compute setups for various needs.
Cons
- −Dependency on Internet Connectivity: As a cloud-based service, a stable and fast internet connection is required for optimal performance.
- −Complex Pricing Structure: While cost-effective, the pricing can be complex due to the variety of GPUs and configurations available.
- −Limited Direct Hardware Access: Users do not have physical access to the hardware, which might be necessary for certain highly specialized tasks.
Limitations & when to consider alternatives
Known limitations
- Card required for the free plan. The $0/month Base plan requires a card on file, and model usage is metered.
- Limited free-tier concurrency. The Base plan includes two concurrent agents, while cancellation returns the account to a one-agent cap.
- Bring-your-own model keys are unavailable. LLM traffic currently routes through Inference's gateway; bringing your own keys is only on the roadmap.
- Only /workspace is preserved across updates. Files outside /workspace, installed software, caches, and home-directory data are reset during VM updates.
- First responses may be slow. The first reply through connected channels can take approximately 30–60 seconds.
Look elsewhere when
- You need a native iOS or Android app.
- You need a browser extension.
- You need shared team workspaces with roles and invites.
- You need fine-tuning on your own data through Ghost.
How to Use Inference.ai
- 1
Explore a range of tutorials and guides available on the Inference.ai website, designed to help users from basic setup to advanced operational techniques.
Who is Inference.ai For?
AI builders
Inference.ai provides hosted models, agent deployment, GPUs, and a unified platform for building AI systems.
Developers
Ghost includes Claude Code and other runtimes, while the platform provides API access to hosted models.
Students and career switchers
Inference Academy explicitly offers programs for beginners, career switchers, students, PMs, analysts, and curious learners.
AI engineers
The Academy and infrastructure products target people building production AI systems, RAG pipelines, agents, and model deployments.
Solopreneurs
Inference Academy offers an AI Solopreneur track focused on building and launching AI-powered businesses.
Frequently Asked Questions
What is pre-installed in the VM?
Ghost includes Claude Code, Hermes, and OpenClaw, plus apt, uv, and npm.
Which models can I use?
Supported model providers include Claude, GPT, Gemini, Groq, and Bedrock.
What happens if I disconnect?
The agent continues running on its dedicated VM, and completed work is available when you reconnect.
How can I customize what runs in the VM?
SSH into the VM to install packages, edit configuration, and add scripts.
Can I use my own API keys?
Currently, LLM traffic uses Inference's gateway through INFERENCE_API_KEY and INFERENCE_BASE_URL; bring-your-own keys are planned.
What happens if I cancel?
Existing agents continue running, while the account returns to the free-tier agent limit.
Community reviews
Be the first to share your experience.
Sign in to leave a review for Inference.ai.
Inference.ai Alternatives
Looking for alternatives to Inference.ai? Here are similar tools in the same category:
Learn to Master Inference.ai
With Skill Leap courses
Get in-depth training on Inference.ai and 50+ other AI tools with our expert-led video courses.
Start 7-Day Free Trial